
Reading inspection output and coverage states
· 4 min read
Read gsc-indexer output: indexed vs not, coverage state, fetch state, robots state, and last crawl time, and what each one tells you.
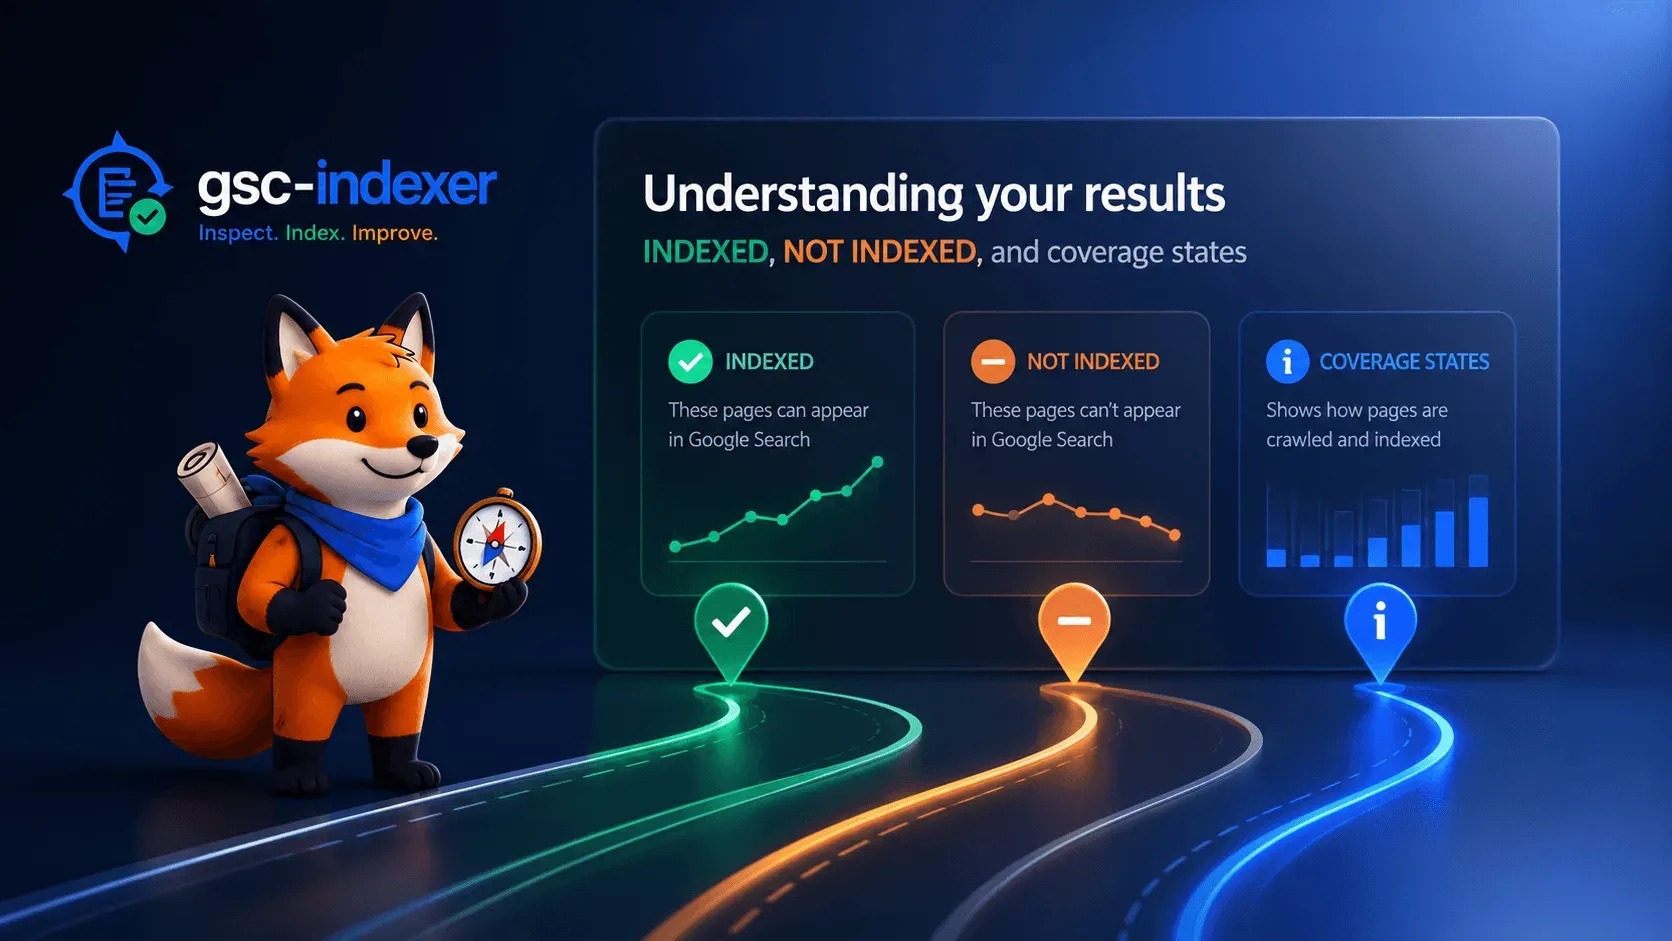
You ran the tool. Now what do the verdicts actually mean?
The two outcomes
✓ INDEXED(green in a terminal): Google's verdict isPASSand the coverage state is not "excluded". Google has this URL in its index.⚠ NOT INDEXED(yellow): anything else: a non-PASS verdict, or an "excluded" coverage state. Google does not currently serve this URL in search. (✗in red is reserved for real errors.)
A NOT INDEXED result is not an error: the inspection succeeded; Google
just doesn't have the page indexed.
Both verdicts from one real run: the first URL is indexed, the second
(a deliberately fake URL) comes back NOT INDEXED:
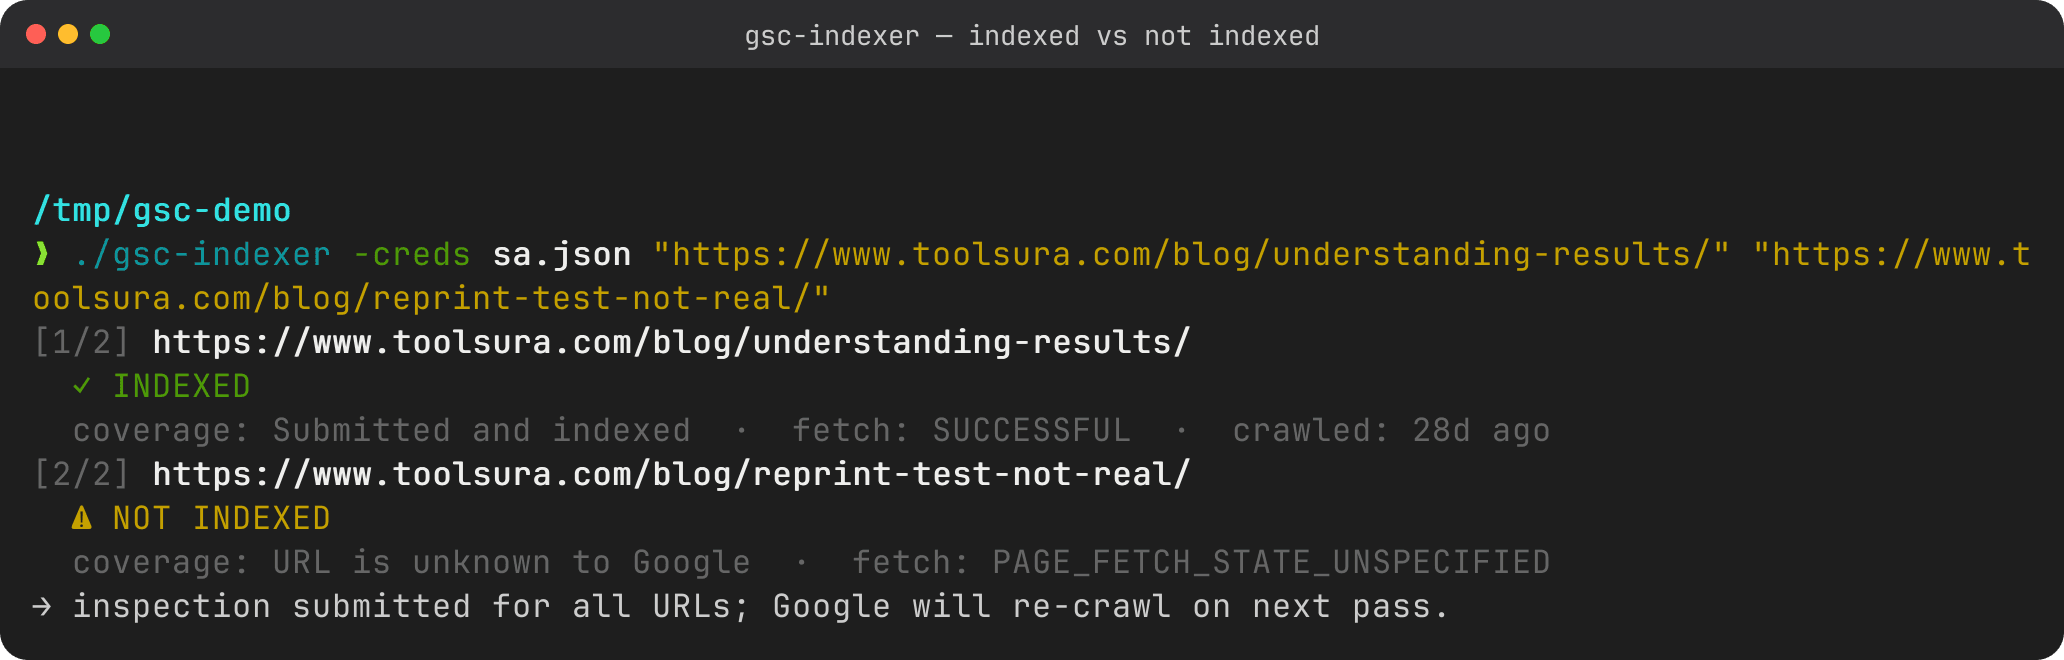
"URL is unknown to Google"
You'll often see this coverage text on a NOT INDEXED result. It means Google
has never indexed the page. To move it toward indexed:
- Make sure the page is live (returns HTTP 200, not a 404).
- Check it isn't blocked by
noindexorrobots.txt. - Submit your sitemap in GSC so Google discovers it.
- Re-run
gsc-indexerto request a fresh crawl, then wait (hours–days).
Coverage states, in plain English
| Coverage state | Meaning |
|---|---|
Submitted and indexed |
Google has it and serves it. |
URL is unknown to Google |
Not indexed yet. |
Excluded by meta tag |
A noindex tag tells Google not to index it. |
Excluded by robots.txt |
robots.txt blocks crawling. |
Crawled - currently not indexed |
Google fetched it but chose not to index (often thin/duplicate content). |
Discovered - currently not indexed |
Google knows of it but hasn't crawled yet. |
The other fields
- fetch. whether Google could download the page (
SUCCESSFUL/ errors). - robots. whether
robots.txtallowed crawling. - last crawl. when Google last fetched it (empty if never).
"inspection submitted; Google will re-crawl"
This line prints after every run. It means the tool asked Google to re-fetch the URL. It does not mean the page is indexed now: indexing is Google's decision and usually takes hours to days to reflect.
"But GSC shows it indexed in 10 minutes!"
When you use URL Inspection in the GSC web UI and click REQUEST INDEXING, the UI polls Google until the crawl finishes, so you watch it flip to indexed. The CLI used to return the pre-crawl state and exit — same API, same request, just no waiting around.
--wait closes that gap. It polls until the URL is indexed (or a timeout you
set):
./gsc-indexer -creds sa.json --wait 15m "https://www.toolsura.com/blog/post/"
  [1] https://www.toolsura.com/blog/post/  [PENDING]  (0s elapsed)
  [2] https://www.toolsura.com/blog/post/  [PENDING]  (30s elapsed)
  [3] https://www.toolsura.com/blog/post/  [INDEXED]  (60s elapsed)
--wait 15m— give Google up to 15 minutes (any Go duration works).--poll-interval 30s— how often to re-check; the default is 30 seconds.- The run exits 0 when indexed, 1 on timeout or error — CI-friendly. (This
is a
--wait-only rule; a plain run exits 0 even onNOT INDEXED.) - Already-indexed URLs skip the poll entirely, so
--waitcosts nothing on routine re-index runs.
Use it selectively: one important fresh URL with --wait, big batches
without (Google doesn't index 200 pages in 15 minutes anyway).
Verdict: PASS vs NEUTRAL
Only a PASS verdict with a non-excluded coverage state counts as indexed. A
NEUTRAL verdict ("URL is unknown to Google") is not indexed, even though
the request was submitted successfully.
Next
- Process lots of URLs: batch, stdin, sitemaps.
- Something broke? Troubleshooting.
Sources
- Google Search Console
- URL Inspection API documentation
- Google Search APIs overview
- Service account OAuth (Google Identity)
- About service accounts (Google Cloud IAM)
- Verify site ownership
- Property types: URL-prefix vs Domain
- URL Inspection tool help (request indexing)
- Indexing API (JobPosting/BroadcastEvent only)
Written by
Abhay Khant
Hi, I'm Abhay Thakor
I'm a developer, builder, and technology enthusiast interested in turning ideas into useful products.
I enjoy working across web development, cybersecurity, automation, SEO, and content creation. Rather than only learning technologies individually, I like putting them together to build things that people can use.
One of my main projects is Toolsura, a free online utility platform that brings practical tools into one place. I'm building Toolsura as a product and a learning project where I can explore development, infrastructure, SEO, content distribution, automation, and product growth.
What I Build
My work currently revolves around several areas:
Web development with Next.js, React, Tailwind CSS, and modern web technologies
Backend development with Go, APIs, databases, and server-side systems
Automation using n8n, APIs, Docker, and connected services
SEO and content systems for building organic search traffic
Cybersecurity including web security, bug bounty, SOC concepts, and malware analysis
Content creation including video editing, YouTube content, graphics, and promotional videos
I enjoy going beyond tutorials and experimenting with complete systems, from the frontend interface all the way to the backend, deployment, automation, and distribution.
Toolsura
Toolsura is one of the projects I'm most actively building.
The idea is simple: create useful, accessible online tools that solve small problems quickly.
Toolsura includes utilities for things such as text, JSON, URLs, PDFs, images, security checks, and other everyday technical tasks.
Building it has also become a practical way for me to learn how a modern web product works.
That means working on:
Product → Development → Infrastructure → SEO → Content → Distribution → Automation → Growth
Technology & Learning
I'm particularly interested in understanding how systems work rather than simply learning how to use them.
My development work has included technologies such as:
Next.js · React · TypeScript · Tailwind CSS · Go · Gin · GORM · PostgreSQL · MongoDB · Docker · RabbitMQ · MinIO · Strapi
I've also worked with Linux environments and tools such as Kali Linux, Termux, and related security tooling.
My cybersecurity interests include web application security, bug bounty research, SOC analysis, and malware analysis.
Building in Public
I also create content around the things I build and learn.
This includes:
Tutorials and technical articles
YouTube videos
Product demonstrations
Visual explainers
Promotional videos
SEO-focused educational content
My goal is to turn projects and experiments into useful resources that other people can learn from.
Why I Build
For me, building is one of the best ways to learn.
Instead of learning a technology in isolation, I prefer starting with a real problem and figuring out what is required to solve it.
Sometimes that means writing code. Other times it's debugging a deployment at midnight, or working out why a page isn't being indexed, why an API isn't behaving correctly, or how to automate something that would otherwise take hours.
Those problems are part of the process.
Every project gives me another opportunity to understand how technology works in the real world.
What I'm Working Toward
I'm continuing to develop my skills across software engineering, cybersecurity, automation, and digital products.
At the same time, I'm building Toolsura into a useful platform and experimenting with different ways to create, distribute, and grow technical products.
There is still a lot to learn, but that's exactly what makes building interesting.
Let's Connect
If you're interested in web development, cybersecurity, automation, SEO, online tools, or building products, feel free to connect.
I'm always interested in learning, experimenting, and building something useful.
Build. Learn. Improve. Repeat.