
What the Google Indexing API actually covers
· 6 min read
Google Indexing API explained: its narrow 2-content-type official scope, service account auth, the 200-per-day quota, and how third-party wrappers fit.
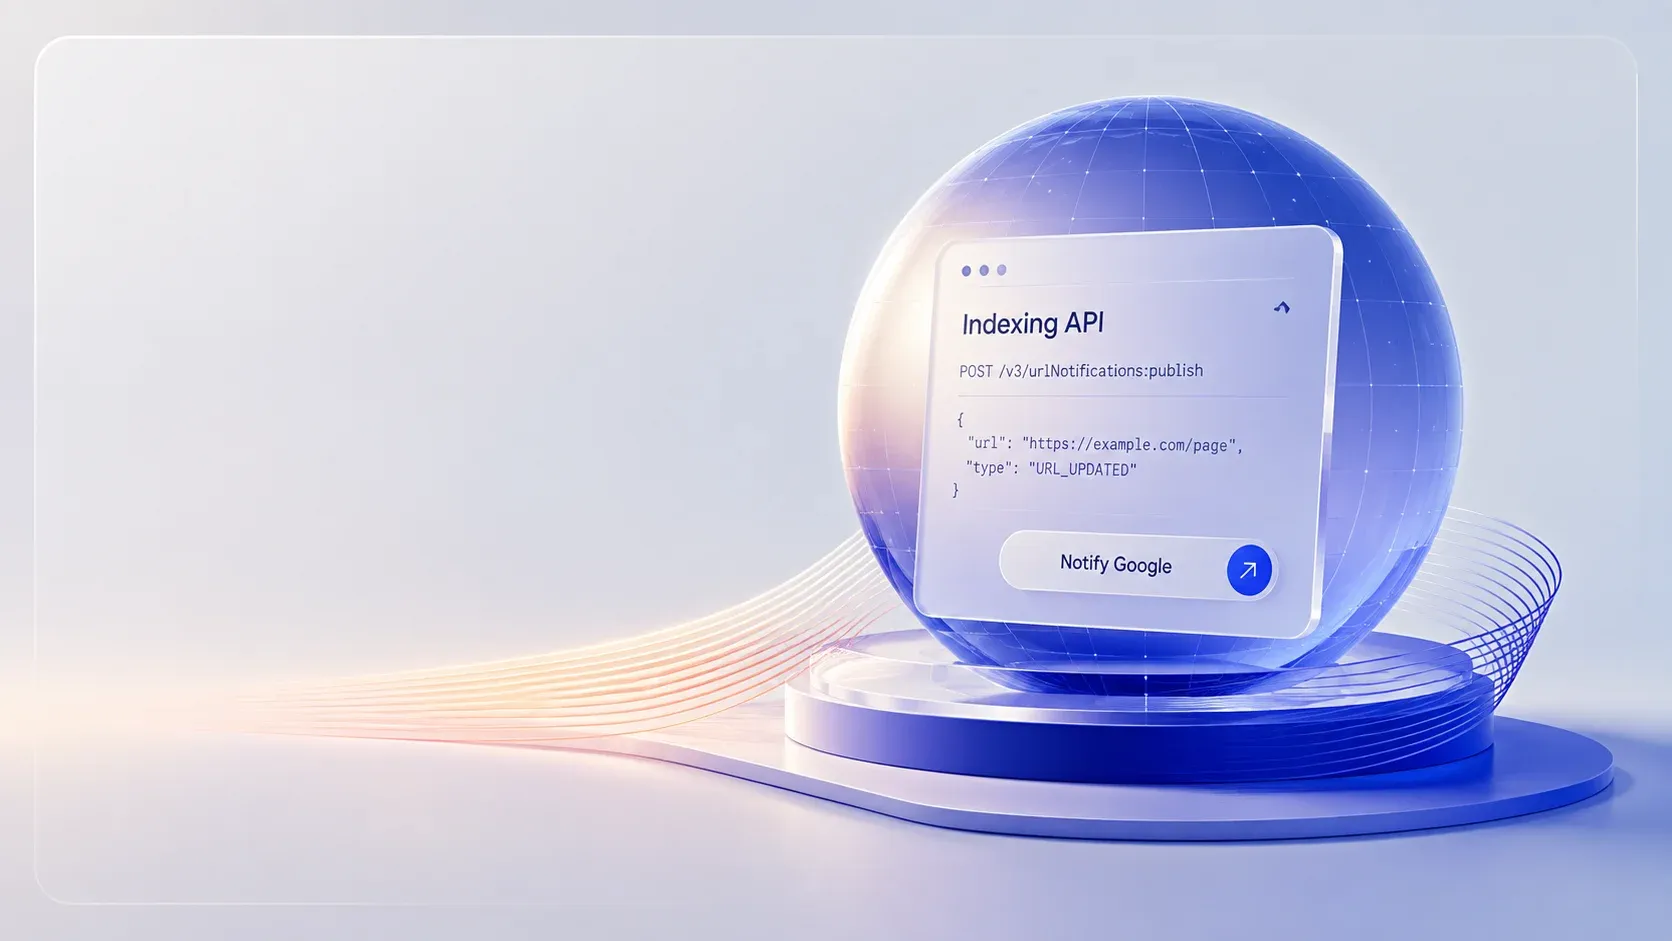
- The API requests crawling directly instead of waiting for discovery
- Officially scoped to job postings and livestream pages only
- Auth runs through a Search Console service account; the default quota sits at 200 requests daily per Google's Indexing API documentation
- Asking for crawl priority never guarantees indexing
Before spending API quota, confirm whether a URL actually needs pushing: Search Console's URL Inspection tool shows the current index status per address.
What the Google Indexing API is
The Google indexing API is a REST endpoint that lets your server tell Google about URL changes immediately instead of waiting for crawlers to discover them naturally. Where normal discovery depends on sitemaps, internal links, and crawl scheduling, the Indexing API quickstart describes the direct path: an authenticated HTTP request asks Google to crawl a specific URL right now. For pages where freshness is the product, such as new job listings or updated schedules, the difference between waiting days and minutes matters commercially. Our indexing timeline guide quantifies what natural discovery usually costs. Mechanically it parallels sitemaps, pushing instead of waiting to be pulled.
The official scope: narrower than people hope
Here is the part most articles gloss over. Per Google's own documentation, the API is officially supported for two content types only: pages with JobPosting structured data and pages with BroadcastEvent (livestream) structured data. Submitting other page types works at the HTTP level but falls outside the documented support envelope.
That gap between what functions and what is supported explains the ecosystem of third-party tools that submit general URLs through the API anyway, and why results for unsupported types vary from fast indexing to silent indifference.
For most sites, the honest decision tree reads: job or livestream pages, use the API as intended. Everything else, rely on a verified Search Console property, quality internal linking, and sitemaps, treating any API wrapper as experimental.
How authentication works
The API authenticates through a service account rather than your personal login. Four steps set it up:
- Create a project in Google Cloud
- Enable the Indexing API for that project
- Generate a service account key
- Add the service account's email as an owner (or delegated owner) of the Search Console property whose URLs you will submit
Ownership linking is the step people miss; without it, submissions fail authorization regardless of valid credentials. Each request signs itself with the OAuth 2.0 service-account flow rather than interactive login. Failures also distinguish themselves cleanly: a permission problem and an exhausted quota return different error codes, so one rejected batch tells you whether to fix access or wait for tomorrow's allowance.
Quotas and request limits
Google publishes a default quota of 200 requests per day per project for metadata updates, which covers small-to-medium sites comfortably but requires quota increases for large job boards. Write requests come in two flavors: urlNotifications/update signals an updated URL and urlNotifications/publish handles both new and updated URLs, while urlNotifications/metadata reports on notifications you already sent. For the exact endpoints and payload shape, the quickstart guide shows both. A minimal submission looks like this:
POST https://indexing.googleapis.com/v3/urlNotifications:publish
{
  "url": "https://www.example.com/jobs/senior-engineer",
  "type": "URL_UPDATED"
}
Quota exhaustion surfaces as an error response rather than a silent drop, and the two failure modes carry separate codes: blowing the daily cap is not the same as tripping the per-minute rate limit. Watching which one you hit tells you whether to request a quota increase or throttle the submission loop.
What submission does and does not guarantee
| Claim | Reality |
|---|---|
| Submission guarantees indexing | No: it requests prioritized crawling, nothing more |
| Indexed means ranking | No: ranking follows separate quality evaluation |
| Faster than natural discovery | Generally yes for supported types |
| Works for every page type officially | No: JobPosting and BroadcastEvent only |
Google's own caveat states plainly that submitting a URL does not guarantee it will be indexed or stay indexed. Anyone promising guaranteed indexing through this API is overselling it.
The third-party wrapper ecosystem
Because manual service-account setup is fiddly, a tool ecosystem wraps the API into point-and-click interfaces: paste a URL list, click submit, watch statuses. ToolSura's own GSC indexer coverage, starting with what the GSC indexer is and continuing through the GSC indexer FAQ, examines that category in depth. In our experience evaluating that category, two criteria separate useful wrappers from risky ones: whether they handle the Search Console ownership binding correctly, and whether they respect the daily quota instead of burning it on retries.
A parallel technology deserves mention for completeness: IndexNow, the joint Bing and Yandex protocol, offers instant submission on those engines with far simpler key-based auth. Google does not participate in IndexNow, which is precisely why its API occupies the niche it does. Under the hood both implement the push-notification model the W3C standardized as WebSub.
Common mistakes with the indexing API
| Mistake | Consequence | Fix |
|---|---|---|
| Skipping Search Console ownership grant | 403 permission errors on every call | Add the service account as property owner |
| Treating submission as guaranteed indexing | Misreading silence as failure | Check indexation via site: queries instead |
| Submitting unchanged URLs repeatedly | Quota burn with no benefit | Submit on real content changes only |
| Using it as the only discovery channel | Crawl dependence on a narrow pipe | Keep sitemaps and links healthy alongside |
When silence follows a submission, resist resubmitting and confirm reality instead, since a site: query settles indexation instantly. Our guide to tracking indexed pages over time turns those spot checks into a trend you can watch.
Using the indexing API wisely
The Google indexing API is best understood as a freshness pipe for exactly two content types. Everything wrapped around it, from service-account ceremony to modest quotas to wrappers of varying honesty, exists to serve that narrow purpose. Use it as designed for jobs and livestreams. Treat general-purpose submission as experimental, and never let it replace the boring fundamentals of sitemaps, internal links, and crawlable architecture. Those fundamentals remain what everything else stands on.
Written by
Marcus Oyelaran
My first move on any indexing problem is to check what the server sends back, because the setting in the content system and the response the crawler received are frequently different things. There are two ways to say do not index, and both have to be in agreement. A robots meta tag in the page, and a header carrying the same instruction.
The header takes precedence, so a page with a noindex tag and a missing header from a misconfigured rule will still be indexed, which is the single most common cause of a page that refuses to leave a result page. A page excluded through the robots file cannot be crawled, so its meta tag is never read, so it cannot be indexed that way either. The file and the tag solve different problems: the file prevents crawling, the tag prevents indexing while allowing the crawl.
Removing a page from a sitemap does not remove it from an index. The sitemap is for discovery. If a page needs to leave an index it needs the instruction, and the instruction takes a crawl to be seen.
Deletion is the slowest path, since removal depends on a crawler revisiting the address, which is an argument for keeping low-value pages rather than deleting them and hoping. I also cover the case that looks like an indexing bug and is not: a page indexed at a different address than the one requested, which is a canonical problem. Each of these is settled by the response the crawler received, so I show that response rather than the configuration that produced it, since the two diverge more often than the tooling suggests.