
Identifying website technology by hand, step by step
· 8 min read
Learn how to detect website technology step by step: HTTP headers, page source, cookies, DNS, and certificates. A manual-first workflow anyone can follow.
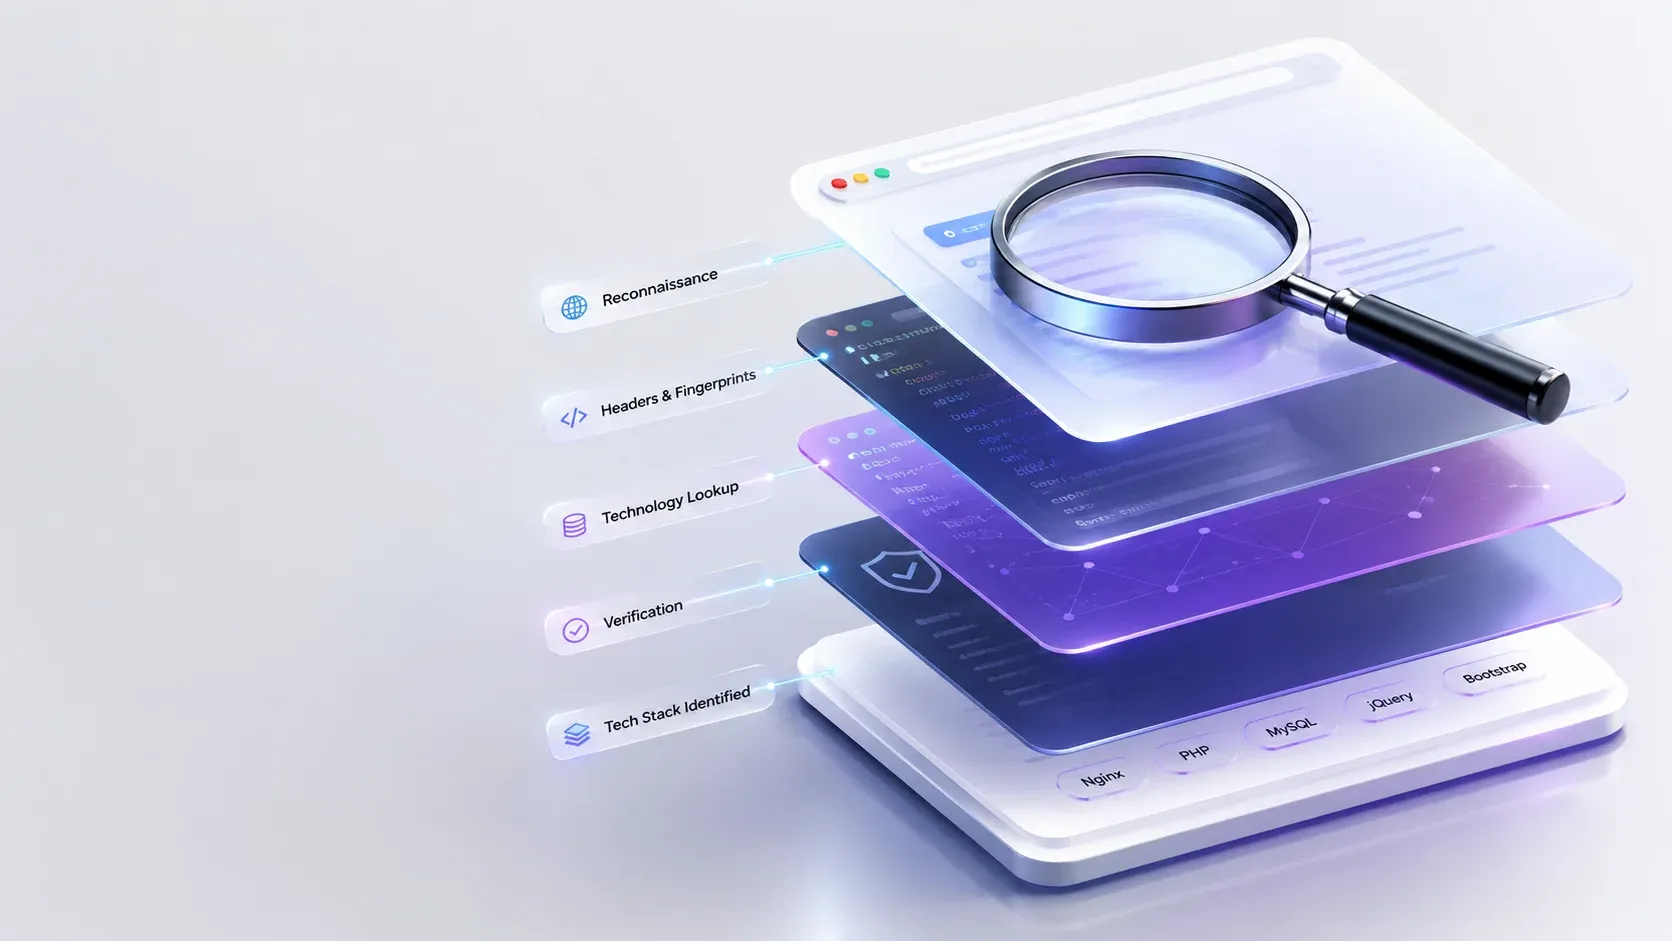
- Start manual: headers, source, and cookies identify most stacks fast
- X-Powered-By and Server name backends; meta generator tags declare CMSs outright
- Asset paths such as wp-content, JS globals like __NEXT_DATA__, and durable cookie names are the fingerprints that survive hardening
- DNS, certificates, and redirect chains reveal the hosting layer
- Verify findings two ways before acting
Why detect a website's technology at all
Knowing how a site is built answers practical questions. You might be evaluating a vendor and want to know whether their platform matches yours. You might be job hunting and want to know which frameworks an employer actually runs. Or you may be debugging why your own site behaves oddly behind a particular CDN, or researching competitors before choosing a stack for a new project. Learning how to detect website technology turns guesswork into evidence.
This guide teaches the workflow in the order practitioners actually use it: free manual checks first, infrastructure signals second, automated tools last. If you want the background theory, the site already covers how detection engines work; this article is the hands-on counterpart.
What counts as ethical website technology detection
Everything in this guide uses publicly observable signals: response headers your browser already receives, source code your browser already downloads, DNS records that are public by design. Nothing here involves probing, scanning, or attempting to bypass access controls, which cross legal and ethical lines in most jurisdictions. Detection from public signals is research; active probing without permission is something else entirely.
Step 1: Read the HTTP response headers
Every web response carries headers, and servers leak their identities in them more often than not. As documented in MDN's HTTP headers reference, two headers do most of the telling:
| Header | Example value | What it reveals |
|---|---|---|
X-Powered-By | PHP/8.2.1, Express, ASP.NET | Server language or framework |
Server | nginx, Apache, cloudflare | Web server or edge CDN |
Via | 1.1 varnish | Caching proxy layer |
X-Generator | Drupal 10 | CMS when sites declare it |
You can view headers in any browser's developer tools (Network tab, click the first request, read Response Headers) or from a terminal: running curl with the head-only flag against the site fetches just the headers, and adding the silent flag suppresses the progress output for scripting. The curl documentation covers the flag variations if you want request methods and redirects in one pass. Many sites strip identifying headers deliberately as hardening, so absence is not proof of absence; it just means the next steps matter more.
Step 2: Inspect the page source
The HTML source is the richest public fingerprint surface. Right-click, View Source, then search for these patterns:
The generator meta tag
Per the HTML specification's meta element, a tag like <meta name="generator" content="WordPress 6.5"> declares the building tool outright. Static site generators (Hugo, Gatsby, Jekyll) commonly emit it too.
Asset paths
Want to detect the CMS of a website without any tools? Script and stylesheet URLs betray platforms through directory conventions: /wp-content/ and /wp-includes/ mean WordPress on sight. Drupal serves from /sites/default/, Shopify pages load from cdn.shopify.com, and Squarespace assets carry its own domain markers.
JavaScript globals and attributes
Source comments leak details too: plugin credit banners and version-stamped comments survive from development into production surprisingly often.
Framework fingerprints live in the runtime: a <script id="__NEXT_DATA__"> blob means Next.js, an ng-version attribute on the root element means Angular, and React root markers in the markup or the bundled React runtime mean React. Search the source for each string; one hit usually settles the question.
Step 3: Check cookie names
Cookies persist across requests and carry platform signatures that survive header stripping. PHPSESSID names PHP sessions, csrftoken points at Django, JSESSIONID indicates Java application servers, and wp-settings- cookies appear on WordPress logins. Per MDN's Set-Cookie documentation, servers set these identifiers on every response that starts a session. Developer tools show them under the Application (or Storage) tab. Cookie names change rarely because renaming them breaks sessions, which makes them among the most durable fingerprints available.
Step 4: Read robots.txt and sitemap.xml
Two plain-text files sit at the root of nearly every site, and both leak platform conventions. The robots exclusion protocol governs robots.txt, and sites routinely declare platform-specific paths in it: disallow rules covering /wp-admin/ identify WordPress, /user/login patterns suggest Drupal, and Shopify stores expose /checkout and cart endpoints. The sitemap file, whose format the sitemap protocol defines, often carries a <generator> declaration naming the CMS or plugin that produced it, mirroring the meta generator tag in the page source.
Fetch both files directly (https://example.com/robots.txt and https://example.com/sitemap.xml) and skim them. The thirty seconds spent there frequently confirms or kills a hypothesis formed from headers alone.
Step 5: Read the infrastructure signals
With the application layer narrowed down, three public infrastructure checks round out the picture of where a site actually runs:
- DNS records. Nameserver hostnames reveal DNS providers, MX records reveal email systems, and TXT records frequently embed SaaS verification strings (
v=spf1 include:_spf.google.comnames Google Workspace, per the SPF specification) - TLS certificate. An SSL checker shows the issuer and validity details; certificates issued through Cloudflare or AWS Certificate Manager hint at the delivery stack
- Redirect chain. A redirect checker traces each hop; as MDN explains redirects, every hop is an observable response, and hop patterns expose CDNs, geo-routing, and A/B testing layers that never appear in the final page source
An IP address lookup adds the hosting answer: resolve the domain, then check which network owns the address block. Sites fronted by major CDNs will show the CDN's network rather than the origin host, which is itself a finding worth recording.
When to reach for automated detectors
Manual inspection answers "what is this site running" for a handful of domains. At scale, or when you need confidence across dozens of signals, a website technology checker or website stack checker pays off. The site's roundup of the best tools to detect website technologies compares the options; the short version is that browser extensions suit quick one-off checks while databases suit bulk research.
Visual confirmation has a place too: the online screenshot tool captures how a site renders, which helps spot admin-bar fragments, preview-mode artifacts, and theme fingerprints that text-based inspection misses.Automated tools also cover what manual inspection cannot: they correlate hundreds of weak signals (asset hashes, string patterns, header combinations) into confident matches. For the mechanics of that correlation, the explainer on how technology detection works goes deep, and the developer-focused fingerprinting guide covers building your own matchers.
A worked example, start to finish
We ran the full workflow against wikipedia.org while writing this guide; every artifact below is quoted from that live run, and you can reproduce it with the same two commands.
- Headers first. A head-only curl request to the site returned
Server: ATS/9.2.15(Apache Traffic Server, a caching proxy) plus anx-cacheheader naming internal cache nodes. Conclusion so far: a custom caching edge; origin software still unknown - Cookies next. The response set
WMF-Last-Accesscookies scoped to.wikipedia.org. The WMF prefix points at the Wikimedia Foundation's own stack rather than a commercial platform - DNS confirms independence. Nameservers resolve to
ns0/ns1/ns2.wikimedia.org: self-hosted DNS, consistent with a foundation running its own infrastructure end to end - Disconfirming check. No generator meta tag, no wp-content paths, and no framework globals appeared in the source. Nothing contradicts the custom-stack reading
Four steps, a couple of minutes, conclusion held to the two-signal standard: Wikimedia-operated infrastructure fronted by Apache Traffic Server. That is the discipline the whole workflow teaches, and it works identically on any public site.
Verify before you conclude
Single signals mislead. A Server: cloudflare header says the CDN is Cloudflare, not that the origin is. A generator meta tag may be stale after a migration. The habit that separates accurate detection from lucky guessing is triangulation:
- Name the hypothesis from your strongest signal (asset paths usually win)
- Find a second independent signal (cookie name, JS global, or DNS record agreeing)
- Look for disconfirming evidence (a Laravel cookie on a "WordPress" site means keep digging)
Two agreeing independent signals put most conclusions beyond reasonable doubt. One signal alone is a lead, not a finding.
The limits of detection
Some stacks resist identification by design. Heavily hardened sites strip identifying headers, bundle assets through CDNs that mask paths, and serve generic markup. Server-side rendering blurs framework boundaries because the output looks like plain HTML regardless of what produced it. And private networks, staging environments behind authentication, and API-only services offer little public surface at all. When detection stalls, the honest answer is "publicly indeterminable," not a confident guess from thin evidence.
The complete website technology detection workflow
To detect website technology reliably: read the response headers, inspect the page source for generator tags, asset paths, and JS globals, check cookie names, then trace DNS, certificates, and redirects for the infrastructure story. Triangulate two independent signals before concluding anything, and escalate to automated detectors when scale demands it. For choosing between those detectors, see the comparison of WappalyzerGo versus Wappalyzer, and for choosing a detector outright, see the Wappalyzer alternatives compared. Bookmark this website technology detection workflow as the playbook the rest of the silo assumes.
Written by
Viktor Petrov
I start on my own domains. Running a subdomain sweep against something I control tells me what the internet sees, which is usually not what the inventory document claims, and it fills me with better examples than a theoretical walkthrough ever would. Subdomain discovery has three reliable sources and a long tail. Certificate transparency logs publish the names a certificate authority has issued for, which catches internal naming conventions nobody documented.
DNS brute force against a wordlist finds hosts with no certificate. Crawling and guessing application names finds the rest. All three drown in noise: wildcard DNS returns the same address for every name, so a naive scanner reports thousands of hosts that do not exist. Status codes are the useful signal.
200 means the host serves content. 301 and 302 mean it exists and redirects somewhere. 403 means the host is there and refusing, which is the answer people most often discard as a failure. 404 is the only real absence, and even that can come from a catch-all server.
Redirect chains hide more than they reveal. A login page three hops away may have been folded into a new marketing site. An infinite loop usually means a misconfigured host. I follow them and report the full chain, because a single hop hides most of the story.
Technology fingerprinting reads headers and generator tags, some honest and some stripped by every current framework. Where a fingerprint comes from a marker file or an error page, I say so, since those are stronger signals. I am consistent about authorisation. Every page states what a request target is and what rate limits apply, because these tools work equally well against a host that has not agreed to it.