
Your PDF shows one page and ships a dossier
· 10 min read
Your PDF hides metadata, text layers and edit history. Learn what no-upload tools keep on your device and which two converters send data.
Open a PDF and you see pages. Select all, paste into a plain text editor, and you may see more than the pages showed: text from scanned layers, words hiding under black bars, comments you never opened. That gap between what a PDF displays and what it contains is why PDF tools with no upload exist, and why "we never see your file" deserves a closer look than a badge.
Four neighbouring guides on this site argue that keeping files off servers is good. None says what an upload actually exposes. This post fills that absence: what travels inside a PDF besides the page image, how to inspect your own file, a byte-level measurement of what a no-upload tool keeps and drops, the two converters that are not private, and the exact boundary of the privacy promise.
Try this first: the 30-second paste test
Run one experiment on a PDF you were about to process online. Open it, press Ctrl+A (Cmd+A on Mac) to select everything, copy, and paste into the plainest text editor you have: Notepad, TextEdit in plain-text mode, anything without formatting. Compare what lands in the editor with what you saw on the page.
Anything extra came along for the ride, and an upload would carry it too. Common surprises include a text layer sitting under scanned page images, paragraphs covered by black rectangles that still paste perfectly, review comments you never opened, and form answers stored as data rather than marks on a page. The test costs half a minute and needs no software. A filing in federal court failed exactly this way in 2019 (more below) when blacked-out passages in a public document gave up their text to a simple copy and paste, as Vox's report on the Manafort filing redaction failure described: "though parts of the public version of this filing appeared to be redacted by black bars, it quickly became apparent that the text underneath those redactions could be revealed by simply copying and pasting from the document."
If your paste reveals text you thought was gone, stop. Do not upload that file anywhere until the hidden content is removed, not merely covered. The redaction section explains the difference and why the browser annotator on this site is a review instrument, never a redaction instrument.
What lives inside a PDF besides the page image
A PDF is a container, not a picture. The visible pages are one compartment among several, and every compartment uploads with the file. Named compartments turn vague unease into a concrete inspection list.
The first compartment is the document information dictionary: a small record carrying Title, Author, Subject, Keywords, Creator, Producer, CreationDate and ModificationDate. These are ordinary settable fields: pdf-lib's document API, the same library these browser tools ship, exposes them directly as setTitle, setAuthor('Humpty Dumpty'), setSubject, setKeywords, setProducer('PDF App 9000') and setCreator. Open any PDF's Document Properties dialogue and you are reading this record. If somebody else authored the file, assume every field is populated with their software, their name and their timestamps.
The second store is XMP metadata, which most readers never see. The Properties dialogue shows the information dictionary; the XMP packet rides alongside it as a separate stream with its own author names, timestamps, edit history and software fingerprints. Standards exist, in the words of Wikipedia's overview of the Extensible Metadata Platform, "for embedding XMP information into popular image, video and document file formats, such as JPEG and PDF, without breaking their readability by applications that do not support XMP." Invisible to the application is the point, and the hazard.
The rest sit at page and object level: the text layer under scans, annotations and review replies, embedded attachments such as source spreadsheets, form field values, and revision history from incremental saves. PDF supports incremental updates that avoid rewriting the entire file, because, as Wikipedia's PDF article notes, the cross-reference layout "also allows for small changes to be made without rewriting the entire file (incremental update)". Each change appends rather than replaces, so an edited file can outweigh its visible content, and the difference can be earlier versions of the very pages you edited. Uploading sends all of it.
Check your own file before you decide
You need not take any of this on trust. Three free inspection routes confirm it against your own documents: the "before you upload" check absorbed here from a retired compressor-title draft.
Start with Document Properties: every mainstream reader has it under File. It shows Author, Title, Creator, Producer and both dates; treat anything filled in as data you are about to hand over.
Then move to the command line. The pdfinfo utility, in the words of its man page on mankier.com, "prints the contents of the 'Info' dictionary (plus some other useful in[formation…]". One command (pdfinfo path/to/file.pdf) dumps the metadata record plus page and object counts that hint at hidden weight. Its documented password flags (pdfinfo -upw password path/to/file.pdf) are themselves a reminder that a password keeps casual readers out without scrubbing the metadata.
For the deeper stores, reach for ExifTool. Its PDF tag documentation explains that "the tags listed in the PDF tables below are those which are used by ExifTool to extract meta information, but they are only a small fraction of the total number of available PDF tags," and confirms it "supports reading and writing PDF documents up to version 2.0, including support for RC4, AES-128 and AES-256 encryption." Encrypted files still carry metadata. One honesty note: the only removal example confirmed in the ExifTool FAQ covers JPEGs, so this post prints no metadata-strip command for PDFs. Verify anything a forum suggests against your own file before believing it.
Finish with checks no utility needed: the paste test, the comments panel, the attachments sidebar, whether form fields highlight. A file much heavier than its visible content deserves suspicion. Run pdfinfo and compare object counts. For the size side of that story, the companion guide on reducing PDF file size explains which weight is structure and which is pixels.
Measured on the live site: what a no-upload tool keeps and what it drops
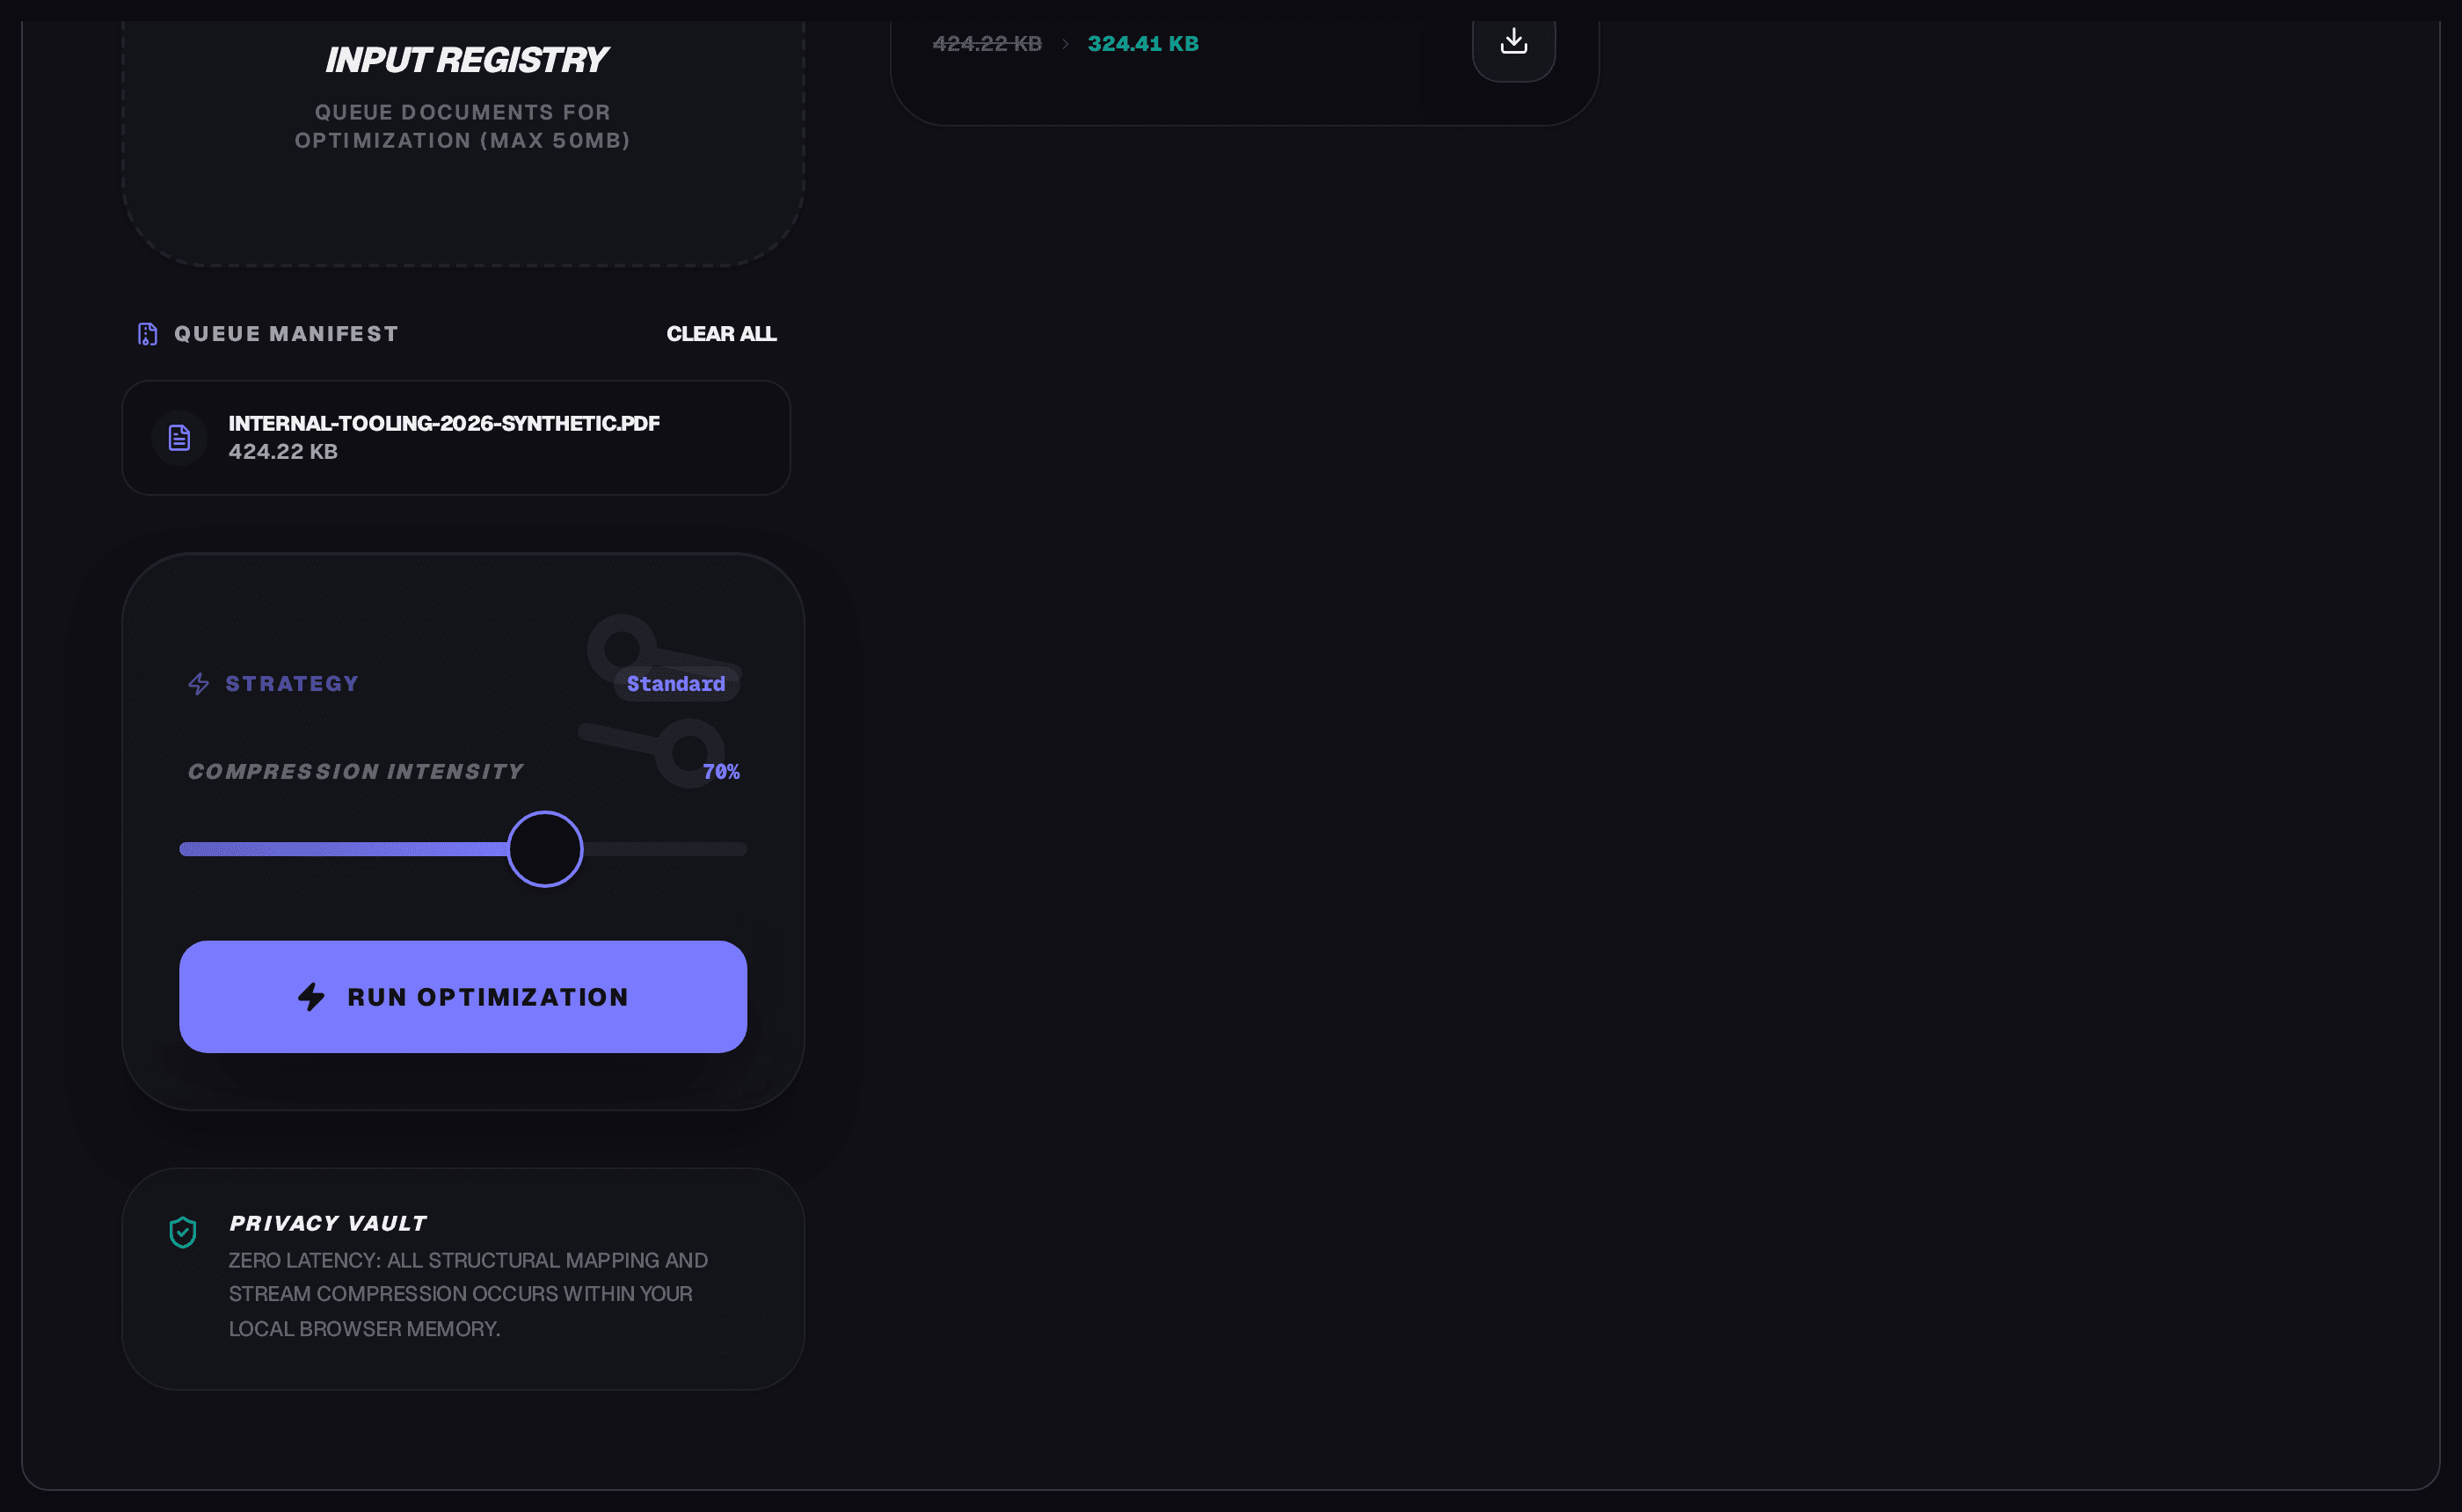
The central question is what a no-upload tool does with it, and here this post states a measured result, not a code prediction. On 12 October 2026, the live compressor at toolsura.com/tools/pdf-compressor/ was run end to end against a stamped 5-page A4 fixture from the same fixture family as the sibling size post: Author set to "Privacy Probe Author", Title to "Probe Document Title", Subject and Keywords filled, custom Creator and Producer values, plus an XMP metadata stream. It went in through the normal page flow, came back through "Export All (ZIP)", and was inspected field by field.
The result: no Author, no Title, no Subject, no Keywords. Creator and Producer both read pdf-lib (https://github.com/Hopding/pdf-lib). CreationDate and ModificationDate were fresh (the moment of processing, not the original timestamps). The XMP stream was gone. All 5 pages survived intact at the same A4 size.
That outcome is better than the marketing version of the claim. The tool does not merely decline to upload your document; its output actively sheds the source metadata by construction. The mechanism is visible in the shipped source: the tool builds a fresh document and copies page nodes across, and page nodes carry page content: the document-level record, the XMP packet, embedded files and form structures have no path into the new file. The stamped fixture went in identifiable and came out anonymous, pages untouched.
Two notes keep this finding honest. It was measured on the compressor path. Merge and split share the same fresh-document construction in source, but only the compressor output was byte-inspected. And the annotator is the deliberate exception: it loads the original bytes and saves the modified document, so document-level data carries over by the same construction logic.
Which tools are no-upload, and the two that are not
Read from the shipped source on 12 October 2026, four tools process document bytes as JavaScript in your tab with no upload, no form post and no document API call in the tool path: the PDF merger and splitter, the PDF compressor, the Word to PDF converter, and the browser PDF annotator, with one load-bearing caveat covered below. The merger and compressor build fresh documents from copied pages; the Word-to-PDF path converts locally through in-browser libraries; none of these tool paths issues a network call for document bytes.
Two tools are not private in this sense. The PDF to Word converter handles plain-text pages locally, but scanned pages take an OCR fallback that sends rendered page images to a server-side Genkit AI flow. The page image leaves the machine on that path by design. The HTML to PDF converter is server-side throughout: the page forwards your input to a server action that calls the third-party pdflayer conversion API, so the target URL and the rendered PDF transit outside your device. Conversion is where client-side processing breaks down, so converter security stands apart as its own subject, and this post does not grade converters by an editor's standard.
The annotator's privacy story has two halves. Document bytes stay local, but it modifies the original document in place rather than building a fresh one, so metadata, attachments and history carry over, and its annotations are image overlays baked onto intact page content. Local processing, uncleaned output. Never a cleaning step.
Redaction is removal, not a black bar
Real redaction deletes content at the object and text layer, verified by the copy-paste test. Everything else is decoration. The 2019 federal-court episode is the permanent exhibit: black bars over a public filing, text fully recoverable by selecting and copying. If your "redacted" PDF yields its secrets to Ctrl+A, the file is not redacted. Do not upload it anywhere. The fix is concrete: keep the original offline, remove the sensitive objects in a tool that edits the content layer rather than covering it, re-export, and repeat the paste test until the editor shows nothing where the secret was.
Two nearby operations are routinely confused with redaction, and neither qualifies. Flattening renders form field values into static page appearance: the pdf-lib documentation lists flattening among form capabilities, ending its flatten example with form.flatten() applied to the form's fields. That is its whole scope: field appearance. It does not remove text-layer content, annotations, attachments, metadata or revision history, because none of those are form fields. And the browser annotator never even reaches that bar: its strokes bake in as an overlaid image while the original page content sits byte-intact underneath, with no content-removal call anywhere in its path. Position it accurately: a review and markup instrument for comments, highlights and signatures; the free online PDF editor guide covers those workflows. Never as a redaction instrument. This site offers no click-here-to-redact flow; the verified core is removal plus the paste test.
The trust boundary, stated exactly
With the merger, splitter, compressor and Word-to-PDF tools, your document's bytes never leave your machine: the code that processes them runs as JavaScript in your tab with no upload, no form post and no document API call in the tool path, verified from shipped source. That guarantee covers document bytes only. The page around the tool still loads scripts the way most sites do, including analytics and consent-gated advertising, the PDF renderer runs from the same site with no third-party CDN in the loop, and anything you type into a URL box or send down an OCR or convert path goes to a server by design. "No upload" means the file stays home, not that the browser went offline. Hold any tool to that sentence.
Honest limits: when uploading is fine
The boundary cuts both ways. Scanned and image-only PDFs cannot be fully served in the tab today: text extraction works locally, but recognising new text from pixels needs the server OCR path, so a scanned private document faces a trade-off rather than a free win. URL-to-PDF conversion is server-side by its nature (somebody's server must fetch and render the page), so treat it as an upload always. Password- and permission-protected files open in these tools through parsing conveniences, not protection; workflows with legal holds, e-discovery or central audit requirements still belong in audited desktop software.
Plenty of uploads are simply fine. A non-sensitive document sent to a processor whose retention and deletion terms you have actually read is an ordinary transaction, not a gamble. For comparing the upload-based suites on those terms (deletion windows, caps, pricing) the guides to iLovePDF alternatives and SmallPDF alternatives cover the server-side landscape this post deliberately does not relitigate. Use local tools where the file is sensitive and upload-based suites where the terms are acceptable.
Four myths worth dropping
A PDF is not what you see: a sentence that dissolves four persistent myths.
A PDF is not a picture of a page; it is a container of compartments. Judging exposure by what renders on screen ignores the metadata record, the XMP stream, attachments, form data and appended revisions, all of which travel silently with every upload.
Flattened is not redacted. Flattening bakes field appearances into the page; the text layer, annotations, attachments and history remain exactly where they were. A flattened file that still pastes its secrets was never cleaned.
No upload is not offline. Document bytes staying home says nothing about the page's analytics scripts, consent-gated ads or same-origin renderer. A guarantee scoped to the file is strong; one scoped to the whole browsing session is a different claim nobody here makes.
A converter is not automatically as private as an editor. Merging, splitting and compressing can run entirely in the tab; recognising scanned text and rendering remote URLs currently call servers. Judge each tool by its data path, not by the suite's badge.
Related tools and further reading
- Reduce PDF file size — the companion piece: what makes PDFs big and which lever actually shrinks them, the source of this post's fixture family.
- PDF merger and splitter — combine or cut documents with the fresh-document construction that leaves source metadata behind.
- PDF compressor — the measured path from this post: shrink files in the tab and get metadata-shedding output.
- Free online PDF editor guide — capability tiers and annotator workflows for review and markup, the correct frame for a tool this post positions as review-only.
Written by
Nikolai Sokolov
My whole beat is the difference between what a document appears to hide and what it no longer contains at all, and that gap is where disclosures happen. Drawing a black rectangle over text does not remove the text. The characters remain in the content stream, and so do they when the file is opened in an editor, copied from, or processed by anything that extracts text. Redaction means rewriting the content stream to omit the characters entirely, and the tool doing it has to be trusted to have done so.
Metadata is the quieter version of the same problem. A document carries a producer, a creation tool, and sometimes an author, and any of those can identify a person or a system you would rather not name. Passwords split into two kinds. An owner password controls whether the file can be opened.
A user password controls permissions such as printing and copying, and it is enforced by the application rather than by cryptography, which is why removing it takes seconds. That distinction matters for compliance work, because a permission password has never protected anything. Encryption strength depends on the revision used.
An early revision uses a scheme with a known weakness, and a later one does not, so two files both described as password protected can differ by orders of magnitude in how long they hold. Every page here says plainly that these controls are deterrents, not boundaries. Signed documents add a further wrinkle, because altering the content invalidates the signature and the whole point of signing was to detect that alteration. Redaction and signing are in tension, and the order they happen in decides which one you end up with.